1. “How Do DiTs Denoise? An Aggregator–Predictor View of Attention and MLPs.” Preprint · arXiv:2610.29854.
Gyeonghun Kang강경훈 · 姜暻勋
Hi there! I am a fourth-year Ph.D. candidate in Statistical Science at Duke University, advised by Simon Mak and Xiang Cheng.
I study how neural network architectures and their components drive model performance across tasks such as language reasoning, image and video generation, and tabular prediction. I first formulate the task and network, then use experiments, mechanistic analysis, and causal interventions to understand what shapes the network's capabilities. These insights guide architectural design and adaptation.
I am currently developing new sampling methods for language models, building on my work on uncertainty quantification for neural operators.
Before joining Duke, I earned an M.S. in Statistics and Data Science and a B.A. in Economics from Yonsei University. Contact me about research or collaboration.
Contactgk149@duke.edu
FollowGoogle ScholarGitHub
News
- Oct 2026Our preprints on DiT denoising and the noise-transmission burden are now available on arXiv.
- May 2026I received the Silver Reviewer Award at ICML 2026.
- May 2026Our paper on in-context posterior prediction was accepted as a poster at ICML 2026.
Selected papers
All papers →-
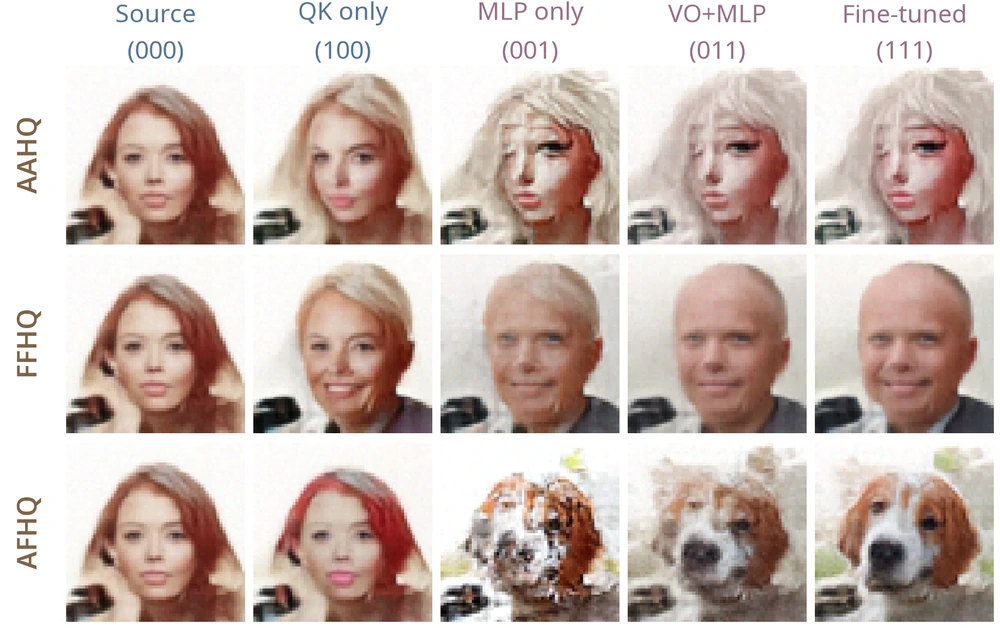
Component swaps from CelebA to AAHQ, FFHQ, and AFHQ (top to bottom). QK (query/key) sets attention weights; VO (value/output) transforms attended features. Codes mark source (0) or fine-tuned (1) weights in QK/VO/MLP order. MLP swaps shift appearance toward the target. Attention gathers context; MLPs denoise
- DiTs perform local denoising: attention gathers relevant patches, while MLPs reconstruct clean patches from learned image representations. Attention reaches farther as noise increases, matching our theory.
- Takeaway: For DiTs pretrained on diverse images, prioritize MLPs for domain adaptation. MLP memory can also be shared across layers, providing a common bank for memory augmentation.
-
2. “The Noise-Transmission Burden of Diffusion Network: Why Image Prediction Can Outperform Noise Prediction.” Preprint · arXiv:2610.34834.

ImageNet256 denoising with an input bottleneck (epoch 200). Noise prediction tracks its theoretical lower bound; EDM (JiT scaling) alleviates the burden at high noise, approaching image prediction. Legend reports guided FID-10K (lower is better). Bottlenecks favor image prediction
- Image, noise, and velocity prediction are not equivalent in finite networks. When model width is smaller than patch dimension, direct noise and velocity prediction incur an irreducible denoising-error floor. EDM preconditioning lowers this floor at high noise.
- Takeaway: For high-dimensional image or video patches, make image prediction the default, especially when model width is limited.
-
3. “Transformers Can Learn Posterior Predictive Distributions In-Context.” International Conference on Machine Learning (ICML).
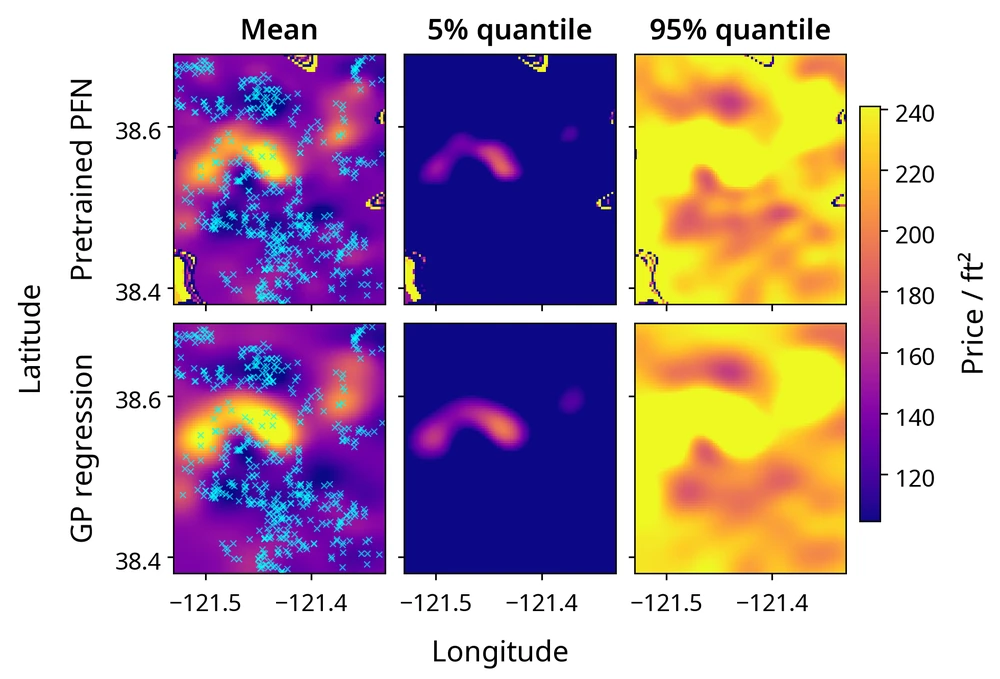
Posterior predictive means and 5th/95th percentiles for Sacramento housing prices. Pretrained PFN (top), GP regression (bottom); cyan × marks indicate context data. Depth gives transformers more inference steps
- Transformers perform Bayesian prediction in a single forward pass: attention layers implement iterative gradient descent, and an MLP converts the result into a posterior predictive distribution.
- Takeaway: For more accurate predictive distributions, give the model more inference steps: add attention layers or use test-time looping.

